Start with v5.5 and an 8 KB reusable buffer
Choose v5.5 C4h with an 8 KB buffer first. Its decruncher is only 476 bytes, it supports Screen 5–8, and 8 KB normally keeps most of the compression benefit while avoiding the packed-size cost of very small chunks. Move to 16 KB when packed size matters most, 1–4 KB when RAM is tight, or v5.6 Direct when the smallest directional Screen 5 file is worth a larger decoder and slower display.
- Drop the source.BIN, PSG and other arbitrary files enter as continuous bytes. BMP, PNG and SC5–SC8 files enter as native image pixels.
- Check the interpretation.For images, verify Screen mode, packed bytes per line and line count. For raw BIN input, geometry must exactly match the data size.
- Select compressors.Recommended runs the active formats. Select all also measures the slower v4.3 historical comparison.
- Run and choose a result.Every candidate is browser-decrunched and compared byte-for-byte before it is offered.
- Download data and code.Choose RAM, RAM-tail, buffered VRAM, linear VRAM or direct VRAM, then use the matching generated or reference source.
Image decruncher size at a glance
476 bytes1–16 KB · 8 KB recommendedBest general size/speed/RAM balance; Screen 5–8.1,398 bytesEight-byte match workspaceNo reusable image buffer is available; Screen 5–8.2,078 bytes32-byte mirrored-row workspaceBest directional Screen 5 packing without a large RAM stage.2,639 bytes1–16 KB in addition to codeA measured horizontal asset benefits enough to justify the larger decoder.813 bytesSmall decoder workspaceA compact older per-Screen backend is sufficient.506 / 665 bytesComplete image / small workspaceCompatibility with the earlier compact-pair image route matters.Illusion City Screen 5 example
The 256×192 IC14_v02.bmp screen contains 24,576 raw bytes. Every buffer choice below uses the same 476-byte C4h decoder and passed exact VRAM verification on the Panasonic FS-A1WSX openMSX profile. The recommended 8 KB route produced 5,201 packed bytes in 1.640 seconds.
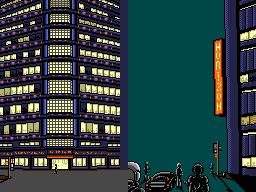
The comparable v5.5 Direct stream uses 4,915 packed bytes and a 1,398-byte decoder but takes 3.721 seconds. There is no universal winner: choose 1–4 KB when RAM is scarce or speed dominates, 8 KB for the usual balance, and 16 KB when the smallest packed file matters most. The selected window may differ for every asset in the same game.
Drop it on the compressor. The page automatically switches to decrunch mode and verifies the recovered bytes locally.
The file type and the data model are separate choices
Continuous data treats every byte as part of one stream. Use it for code, maps, text, sound, Screens 1–4 data and any image whose rows should be joined without a rectangle rule. Image modes preserve row geometry so v5.5 can test whole-line offsets and the generated decoder can write an exact rectangle.
128 bytes256-pixel images128 bytes512-pixel images256 bytes512-pixel images256 bytes256-pixel imagesNative BMP/PNG import removes the file header, palette records and row padding, then converts pixels to the selected MSX packing. A valid seven-byte BSAVE header in SC5–SC8 is detected and removed. Changing Screen 5/7 after importing an image does not silently change the imported packed width.
Smallest verified file wins—within the selected routes
Includes the CBS header
The displayed and downloaded size is the complete packed file, not payload only.
Round-trip proof
The JavaScript decoder reconstructs the source and compares every byte before a result can win.
Same image payload
For a paired image result, only destination bits change. Recompression is not required.
Measured baseline
The proven older aligned-cost engine remains available for comparison and legacy integration.
The three-byte v5 header plus token and EOS bits can exceed a very small uncompressed file. The result table reports the real total.
One byte selects format, variant and destination
Linear files use bytes 1–2 for the complete packed-file length in little-endian order. Image destinations 3 and 5 instead use byte 1 for packed NX and byte 2 for NY; zero represents 256. CBS v4.3 is separate and keeps its established 24-byte CB5 container.
00h / 80hv5.2 compact pairRAMTwo CBS offset representations01h / 81hv5.2 compact pairRAM-tailSame payload, safe relocation route40h / 48hv5.3 / v5.4RAMCombined state-flow decoder41h / 49hv5.3 / v5.4RAM-tailMeasured in-place tail route42h / 4Ahv5.3 / v5.4Linear VRAMTiles, fonts and screen streams43h / 4Bhv5.3 / v5.4 imageBuffered VRAMRAM stage, then HMMC45h / 4Dhv5.3 / v5.4 imageDirect VRAMCPU, HMMM and HMMV backendC3h / C5hv5.5 line-awareBuffer / directIdentical payload after byte 0C4hv5.5 reusable bufferChunked HMMCOne call; each chunk ends with EOSThe selected/generated decoder supplies the reader for RAM, plain ROM or one cartridge mapper. This keeps every data file smaller and avoids carrying unused mapper choices in a game.
Literals establish bytes; matches repeat history
A v5.3/v5.4 stream begins with an interlaced-gamma literal length, followed by those literal bytes. After a literal, one control bit selects a previous-offset match (0) or a new offset (1). After a match, 0 returns to literals and 1 selects another new offset. A previous-offset match saves the complete offset code.
gamma length + raw bytes
gamma match length; reuse the saved negative distance
distance representation + first match-length control bit
Interlaced gamma value
value = 1
while GET_BIT() == 0:
    value = (value << 1) | GET_BIT()
return value
The general distance stores a complemented negative offset. For a positive look-back distance d:
high      = floor((d - 1) / 128) + 1
low       = (d - 1) % 128
packedLow = (127 - low) << 1 | firstLengthControlBit
v5.3 reserves general offset-high 256 as EOS. v5.4 adds one selector before every new distance: 0 codes near distance 1–15, while 1 uses the complete general representation. v5.5 uses its selector for a whole-line distance or the general compact representation.
Sixty bytes become eleven
The verified v5.4 result for ABC repeated twenty times is:
48 0B 00 71 41 42 43 50 3A AA AC48headerv5.4 adaptive-near, linear RAM destination
0B 00packed length11 bytes total, little endian
logical token 1literal 3raw bytes 41h 42h 43h = “ABC”
logical token 2new distance 3copy 57 bytes from the already reconstructed ABC sequence
finishEOSthe impossible general offset-high value ends the stream
Control bits, literal bytes and offset data share the payload, so the remaining hex bytes do not each correspond to one complete token. The logical sequence is the reliable way to read it.
The low three bits say what the decoder must do
Linear RAM
Normal forward reconstruction.
RAM-tail
Relocate packed bytes to the destination tail, then expand.
Linear VRAM
Continuous VDP memory using the current Screen physical width.
Buffered image
Expand into RAM, then upload an exact NX × NY rectangle.
Reusable buffer
Independent v5.5 chunks reuse IX; EOS uploads and advances Y.
Direct image
Reconstruct with CPU writes and VDP commands.
Mapped RAM
Planned MSX Memory Mapper destination.
Normal output or measured destination-tail reuse
The combined v5.3/v5.4 RAM decoder accepts the complete three-byte header at HL:
    LD      HL,PACKED_DATA
    LD      DE,OUTPUT_BUFFER
    CALL    CBS_V5354_RAM_TO_RAM
v5.2 uses CBS_V52_RAM_TO_RAM. CBS v4.3 has its own compatible source because its container and token grammar predate v5.
Generic RAM-tail entry
    LD      HL,PACKED_DATA
    LD      DE,OUTPUT_BLOCK
    LD      BC,UNPACKED_SIZE
    CALL    CBS_V5354_RAM_TAIL
The generated per-file wrapper stores the unpacked size as CBS_FILE_RAM_TAIL, so a game normally supplies only HL and DE. The routine copies the packed file backward with LDDR to the end of the destination block, then performs the usual forward expansion.
The compressor checks every write position against unread packed input. An unsafe file is never offered as a tail build. This is the corrected replacement for the old four-byte-margin assumption.
This is useful when a title screen can temporarily reuse map RAM, or when packed bytes are copied to the end of a buffer before the original content is needed. The compact decoders intentionally do not carry corrupt-stream bounds checks; use them for trusted game-built assets.
Choose the best traversal, then rebuild repeated rectangles in VRAM
v5.6 treats a Screen image as two-dimensional data. The compressor can test horizontal rows in both directions and vertical columns in both directions, then keeps the smallest permitted result. You may restrict the search to Horizontal or Vertical when build time matters. The chosen base uses the proven v5.5 line-aware grammar; CBM1 then appends reconstruction commands for exact, horizontally mirrored, vertically mirrored and two-axis-mirrored 8-pixel-aligned rectangles.
v5.6 is particularly effective on tilesets and tile-like screens containing repeated or mirrored 8–32-pixel regions. Its 2,078-byte Direct decoder is much larger than v5.5 C4h at 476 bytes and usually displays more slowly, so compare total packed data plus code. Start with v5.5 8 KB; choose v5.6 when its directional savings repay the extra 1,602 bytes of decoder.
Rows or columns, forward or reverse
One decoder accepts rows top→bottom, rows bottom→top, columns left→right and columns right→left. The stream records the winner.
Rectangle reconstruction
Compatible adjacent matches are coalesced into larger VDP HMMM operations. Mirrored rows use VDP commands or the decoder's 32-byte row workspace.
No full-image RAM stage
Raw base bytes are delivered to their final Screen 5 rectangle and reconstruction stays inside that destination VRAM area.
Optional rolling output
The packed CBM1 file is unchanged. A caller-selected RAM window can accumulate horizontal base output before VRAM delivery; measure it per asset.
The dedicated Z80 backend supports Screen 5 and all four traversal orders through the stable E000h, E003h, E006h and E009h entries. Screen 6–8 CBM1 results remain analysis-only until their pixel-specific backends are implemented.
Direct and rolling builds use the same call
    CALL    CBS_INIT_MSX

    LD      A,5
    CALL    CBS_INIT_SCREEN

    LD      HL,PACKED_CBM1
    LD      DE,0000h            ; packed X=0, Y=0
    XOR     A                   ; destination page 0
    CALL    CBS_DECRUNCH
The current Direct decoder is 2,078 bytes; each selectable rolling build is 2,639 bytes plus its caller-reserved 1, 2, 4, 8 or 16 KB RAM window. On a complete 32 KB tile-image benchmark, Direct restored exact VRAM in 7.831 seconds on the Panasonic FS-A1WSX openMSX profile and was faster than the measured v5.4 and v5.5 Direct routes. Rolling delivery currently benefits horizontal streams most; vertical streams should be compared against Direct before committing RAM.
One public interface, several delivery backends
The generated image binary exposes three stable entry points:
E000hCBS_INIT_MSXDetect and patch the real MSX VDP ports.
E003hCBS_INIT_SCREENSupply Screen mode 5, 6, 7 or 8.
E006hCBS_DECRUNCHDecode the selected buffer, linear or direct route.
    CALL    CBS_INIT_MSX

    LD      A,7
    CALL    CBS_INIT_SCREEN

    LD      HL,PACKED_IMAGE
    LD      DE,(PACKED_X << 8) | Y
    LD      A,VRAM_PAGE << 2
    CALL    CBS_DECRUNCH
For image routes, D is the packed X byte and E is Y, making DE = XY. A bits 3–2 select the VRAM page. HL points to the three-byte CBS header. IX is required only by the buffered route and points to its RAM stage.
RAM stage + HMMC
C3h expands one complete rectangle. C4h expands independent EOS-terminated chunks, uploads each with HMMC and reuses the same IX buffer.
v5.3/v5.4/v5.5 direct VRAM
Literals use the CPU VRAM port, matches of one to eight bytes use a dedicated RAM buffer, longer matches use HMMM, and long offset-one runs use HMMV.
Tiles and fonts
Write a continuous stream while respecting the physical Screen line width; no NX × NY rectangle is required.
Wait only when needed
VDP-to-VDP commands must finish before the next command. CPU data may be sent through the normal VRAM port while a different command area is active.
Which delivery route should I use?
directbufferedrollingdirectmixedKeep both measured choices. v5.6 Direct gives the smallest directional streams without a large RAM stage. The 476-byte v5.5 buffered decoder is dramatically faster when a reusable 1–16 KB block is acceptable; C4h performs every split and Y advance inside one call.
Reuse a selected v5.5 buffer for a larger image
Choose the RAM budget when compressing. The compressor fits as many complete Screen rows as possible in each independent v5.5 stream and writes a C4h container. EOS ends each chunk naturally; the decoder uploads it, advances Y through the alternate register set and reuses IX.
    LD      HL,PACKED_C4_IMAGE   ; internally chunked for chosen buffer
    LD      DE,0000h            ; packed X=0, Y=0
    LD      IX,8000h            ; reusable 1/2/4/8/16 KB stage
    XOR     A                   ; destination page 0
    CALL    CBS_DECRUNCH
EIIn that 32 KB test, the 16 KB C4h payload is 11,726 bytes; its 1 KB speed-first form is 14,554 bytes. Burai's earlier four-stream proof totals 7,897 packed bytes. Every timed run was checked against the expected VRAM bytes on a Panasonic FS-A1WSX openMSX profile. These are practical measurements, not a guarantee for every image: sparse chunks can be dominated by setup time, so benchmark the intended split points.
Initialize the VDP interface once
After copying the decoder into writable RAM, call CBS_INIT_MSX once before displaying the first image. It reads the BIOS VDP data-port values from 0006h and 0007h, then patches every immediate CPU-transfer, status and indirect-command port operand. The same decoder therefore works when a machine's VDP ports differ from the standard 98h–9Bh addresses.
The direct backend uses a dedicated eight-byte RAM buffer for non-overlapping matches of one to eight bytes. Larger matches use HMMM, while long offset-one runs may use HMMV. This buffer is decoder working memory; it does not require another initialization. Call CBS_INIT_SCREEN initially and again whenever the Screen mode changes.
Direct matches are divided at destination-row boundaries, source-row boundaries and overlap limits. The one-to-eight-byte scratch threshold and the 64-byte fast-fill threshold belong to the decoder, not the packed format, so they can be tuned without recompressing the image. A size-focused build restricted to the standard VDP ports may hard-code them and omit CBS_INIT_MSX; the supplied source retains portable initialization.
One mapped decoder handles buffered and direct images
The Screen 5–8 generator compiles exactly one reader for ASCII8, ASCII16, ASCII16-X, Konami or Konami SCC. The game supplies HL as the exact address in the mapper window and BC as the initial bank. The reader detects the active window, patches its fast path and advances banks whenever HL reaches the boundary.
A file may cross consecutive ROM banks. The generated reader makes that transition while the token decoder continues normally.
The website demonstration keeps page 0 for startup and code, starts packed assets on page 1 by default, runs the decoder at E000h and mapper control at F500h, and leaves 8000h–DFFFh as a 24 KB buffer. Its multi-screen ROM and export table are visualization tools; the CLI intentionally generates only one-image test ROMs. In a mixed ROM, destination 3 expands into the shared 8000h–DFFFh stage and uploads with HMMC; destination 5 reconstructs directly in VRAM. The same E000h/E003h/E006h decoder entries dispatch both routes. For a fair visual comparison, the demo controller sets the border and backdrop to the darkest available palette colour and clears the complete Screen 5–8 VRAM page with HMMV before each image. It waits for the command to finish while restoring status register 0 between CE checks, allowing normal MSX interrupts, and holds the completed black clear for one video frame before starting the decoder. Buffered output appears only after RAM expansion; direct output can be watched as it is reconstructed in VRAM. The harness also disables sprites after each Screen-mode initialization. This prevents stale sprite attributes from appearing over test images and leaves more VDP time available to the decoder.
Cartridge ROM mapper input is implemented for buffered and direct Screen 5–8 output. Output into selected MSX Memory Mapper RAM segments is still planned.
The website engine without the browser UI
Requirements: Python 3.10+, Node.js 22+, and Pillow only when importing BMP/PNG.
# Recommended continuous-data compressors
python cbs_cruncher.py game.bin

# Include every comparison, including v4.3
python cbs_cruncher.py game.bin --compressors all

# Build a measured RAM-tail result
python cbs_cruncher.py game.bin --ram-tail

# Screen 7 image and a one-image test ROM
python cbs_cruncher.py picture.png --mode 7 --rom

# Linear Screen 5 VRAM data
python cbs_cruncher.py tiles.bin --linear-vram-screen 5 --rom

# Decrunch an existing CB5 file
python cbs_cruncher.py packed.cb5 --decompress
Run python cbs_cruncher.py --help for the exact mapper, geometry, search-window and output switches in the current package.
Most failures are geometry, route or host limits
For raw BIN input, packed bytes per line × line count must equal the file length. A seven-byte SC5–SC8 BSAVE header is removed only when valid.
Large image searches are expensive. Use the recommended 2 KB window first; the progress bar shows the current engine and measured work.
Use the local WebMSX button. CBS Cruncher opens a dedicated player tab and transfers the full ROM through browser memory, so 128 KB cartridges do not enter the address bar and are never uploaded. The player selects Japanese MSX2 NTSC and applies the chosen mapper format automatically.
The exact overlap trial found that unread packed bytes would be overwritten. Use normal RAM output or a different destination block.
Use imported palette data where available and test with the Japanese MSX2 NTSC machine; regional default palettes can differ.
The small game decrunchers trust their input and omit defensive bounds checks. Verify files with the browser or CLI before placing them in ROM.
Finish missing delivery paths only when they solve a real asset
- MSX Memory Mapper RAM output.Define the destination-6 contract, selected segment/window parameters and safe crossing between RAM segments.
- Cartridge-ROM to ordinary RAM.The mixed Screen 5–8 reader is complete; a future compact-data route may reuse it for code, maps or other linear RAM destinations.
- Experimental CBT1 follow-up.Revisit its 2,481-byte Screen 5 decoder and possible Screen 6–8 backends only if measured assets justify the extra code.
- Optional hybrid image path.Destination 4 remains reserved for row/chunk history or another mixed strategy only if measured game data justifies its code.
- More game validation.Continue code-size and speed tuning against real maps, tiles, fonts and Screen 5–8 assets without changing verified payloads unnecessarily.
CBS v5 keeps spare destination and variant values so experiments do not force another container redesign. Only implemented routes are shown as downloadable winners.
Use the smallest source set your game needs
← Return to the compressor or review the dated project history.
Tile-grid research retained for comparison
CBT1 can reconstruct exact and mirrored tile rectangles, but its current Screen 5 decruncher is 2,481 bytes—more than five times the recommended 476-byte v5.5 C4h decoder. It is kept as an experiment for assets where tile mirroring saves enough packed data to repay that code cost.
The current backend supports Screen 5 tile grids and the shared E000h/E003h/E006h/E009h calling convention. Screen 6–8 hardware backends and mapped-ROM input remain unfinished. For normal tilesets, platforms and bitmap objects, try v5.5 8 KB first and compare the complete packed-data-plus-decruncher footprint before selecting CBT1.